The nine IT outage notification templates below cover what a service desk sends employees from the first notice to the reason-for-outage summary, with [placeholders] for the system, the scope, the workaround and the next update.
The wording is rarely what goes wrong. The notice goes out late, or through the channel that is down.
Then the help desk is swamped by callers reporting the same problem: agents log duplicate tickets against the major-incident record, users who are actually blocked wait behind them, and the bridge is interrupted by the service desk and managers asking for updates.
Scale adds its own failure points: several sites and time zones, shift workers who start after the first notice has gone out, and contractors without a directory account.
These templates cover failures of IT systems. If the building has lost power, use our power outage notification templates instead.
Read more: 16 Common Helpdesk Problems and How to Solve Them
Table of Contents
1. Seven decisions the outage communication plan settles before the incident
2. What an outage communication template should include – the workaround and the next update first
3. Nine system outage notification templates, from the first notice to the reason for outage
4. To notify all employees about a system outage, choose a channel that does not depend on the failed system
5. Outage notification software turns the plan into saved notices, recipient groups and a resend list
6. Frequently asked questions
Seven decisions the outage communication plan settles before the incident
The post-incident review will ask when the first notice went out, to whom and through which channel, and the only defensible answer is the one agreed on before the incident. That agreement is the communication plan: an incident communication runbook gives the plan its structure, and the nine templates below give it its wording. The plan should settle seven things:
- Facts before cause. Say what is confirmed and what it affects. If the outage may have an internal cause, save the cause for the reason-for-outage message, sent once the root cause is confirmed and the wording signed off; accountability belongs in the post-incident review, not in an all-staff notice.
- Honesty about the unknowns. If engineering cannot stand behind a restoration time, say so and give the time of the next update instead; a missed estimate costs more trust than no estimate.
- Symptoms, not components. “You cannot open files on the S: drive” tells employees whether they are affected; “SAN controller fault” does not.
- A first-notice target. Agree on the maximum time between declaring a major incident and sending the first notice (for example, 15 minutes for a priority 1, even with the cause unknown) and the update interval for each priority level.
- Scope rules for the first hour. Early in an IT outage the scope is often unclear: notify too widely and people learn to ignore notices, too narrowly and the calls come anyway. Agree on who sets the scope, and map each critical system to its user groups in advance – application users rarely match directory groups cleanly.
- A channel that survives the failure. For each critical system, note which channels fail with it: a Microsoft 365 outage can take email, Teams and a SharePoint intranet down together; pop-up alerts need the alerting server to be reachable from the computer; and SMS and the recorded message on the help desk line reach the people the other channels miss.
- A named owner. The incident manager runs the fix; someone else – the service desk lead or an incident communications lead, with an after-hours deputy – owns the notices. Security notices usually need a security approver as well, and legal where personal data may be involved. Pre-approve the security template with them, so that during an incident the first notice needs only one sign-off.
What an outage communication template should include – the workaround and the next update first
In an outage or downtime notification, the workaround and the time of the next update do the most to stop repeat calls.
In full, a notice covers:
- The symptom in the user’s terms, and the systems that depend on the failed one – a single sign-on fault can lock users out of every application behind it.
- The scope: company-wide, one site or region, or one group such as remote staff on the VPN.
- Whether to open a ticket: “no need to report this” stops duplicates, and “report it only if you see it outside [scope]” still lets you find the edge of the outage.
- The workaround, or a plain “there is none yet – wait for the next update.”
- An incident reference, so agents can link the contacts they still receive.
- The estimated restoration time, when engineering has one.
- The time of the next update, and a promise to send it even if there is nothing new.
For the first system down message, when there is no time for the full list, keep a five-line checklist in the runbook, where the notice owner can reach it. We call it ALERT:
A – the affected APPLICATION and the symptom users see
L – the LOCATION or group affected
E – the EVENT: planned or unplanned, and since when
R – the workaround until the RETURN to service, and the time of the next update
T – whom to TALK to, and whether a ticket is needed at all
Nine system outage notification templates, from the first notice to the reason for outage
All nine are written for employees, not customers. Apart from the network one, each works as a system outage email template, with a subject line, or as the text of a desktop alert. Replace the [placeholders] and cut what does not apply.
Planned Maintenance Notification
Subject: [System] unavailable on [date], [start time] to [end time] [time zone]
Hi [team or department],
[System] will be offline for planned maintenance on [date] from [start time] to [end time] [time zone]. You will not be able to [log in / submit requests / open shared files]. Please save your work before [start time]. For urgent needs in that window, contact [name] at [extension or chat channel]. Change reference: [change number].
[Name], IT Service Desk
For reminders and follow-ups, see our scheduled maintenance message templates.
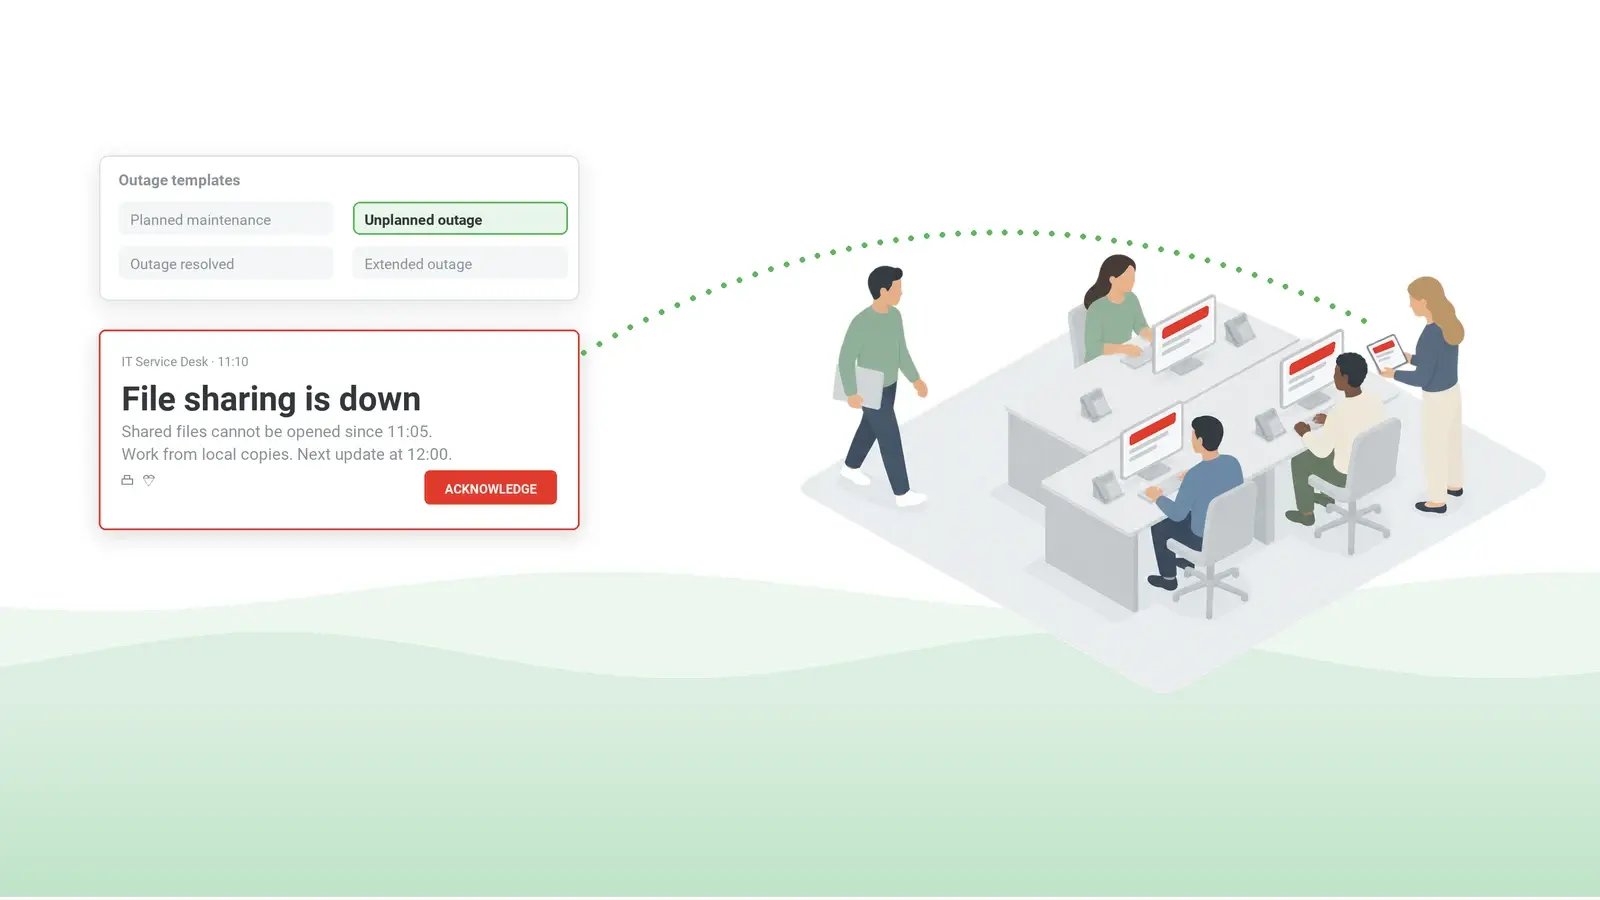
Unplanned Outage Notification
Subject: [System] is down – IT is investigating
Hi all,
Since [time], [system] has not been working for [affected group or location]. IT is investigating; the cause is not yet known. You do not need to report this to the help desk unless you see it outside [affected group or location]. Until it is fixed, [workaround]. Reference: [reference number]. Next update by [time].
[Name], IT Service Desk
Network or Internet Outage Notification
Send this one by SMS or mobile push: affected computers may not receive a desktop alert. Keep it within 160 characters and leave out curly quotes and en or em dashes, which can switch a text message to a format that fits only 70 characters; plain hyphens are fine.
[Company] IT: network down at [site] since [time]. Wi-Fi, internet and shared drives affected. No need to restart your PC. Next update [time] by text.
Degraded Performance or Service Interruption Notification
Subject: [System] is slow – some features affected
Hi [team],
[System] is running slower than usual, and [feature] may fail. If a task fails, wait [number] minutes before you retry, so it is not submitted twice. We are working on a fix and will update you by [time]. No need to open a ticket.
[Name], IT Service Desk
Third-Party Service Outage Notification
Subject: [Vendor service] outage affects [system]
Hi all,
[Vendor] has an outage on its side that affects [system or feature]. We cannot fix it ourselves, but we are following [vendor]’s status updates (its reference: [vendor incident ID]). In the meantime, [workaround]. We will update you by [time], or sooner if [vendor] restores the service.
[Name], IT Service Desk
Security Incident Notification
Subject: Action needed: access to [system] restricted
Hi all,
We have restricted access to [system] while we investigate a possible security issue. Until further notice, please do not open links or attachments in messages about [topic], and report anything unusual to [contact or channel]. IT will never ask for your password or a sign-in code. If you have already clicked a link or entered your password, tell [contact] now. Next update by [time].
[Name], [IT Security team]
Extended Outage Notification
Subject: Update [number]: [system] still down, new estimate [time]
Hi all,
[System] is still unavailable because [one-line confirmed reason in plain words, or “the cause is still being investigated”]. Our new estimate is [time]. Until then, [workaround]. If a deadline depends on [system], tell [contact] so we can help you prioritize. Next update by [time].
[Name], IT Service Desk
Outage Resolved Notification
Subject: Resolved: [system] is working again
Hi all,
[System] has been working normally since [time]. If you still see problems, restart [application] first, then contact [contact] and quote [reference number]. Requests submitted during the outage [have been processed / need to be resubmitted]. Thank you for bearing with us.
[Name], IT Service Desk
Reason for Outage Summary
Subject: What happened with [system] on [date]
Hi all,
On [date], [system] was unavailable from [start time] to [end time] for [affected groups].
What happened: [cause in plain words].
What we did: [steps taken to restore service].
What we are changing: [steps to prevent a repeat].
What you need to do: [nothing / resubmit X].
[Name], [IT manager title]
Whichever templates you use, try each once in a quiet week, so the wording and the recipient groups are ready before you need them.
Download all 9 IT outage notification templates
The download puts the nine notices above in one file.
Download free message templates
To notify all employees about a system outage, choose a channel that does not depend on the failed system
Notifying all employees about a system outage takes three things: the channel, the recipients and the follow-up.
Choose the channel. An intranet banner waits for someone to open the intranet, and some help desks turn to the pop-up commands built into Windows instead; our guide explains how to send a pop-up message to all computers on a network that way and what those commands cannot do.
Match the channel to the urgency:
- Urgent: a desktop pop-up alert on the employee’s screen.
- Ongoing status: a scrolling ticker at the top or bottom of the screen.
- Locked or idle computers: lock screen and screensaver messages.
- Away from desks, or the office network is down: SMS, a text-to-call voice message or mobile push.
Target by audience. Send the notice only to the groups or organizational units, synchronized from Active Directory, that use the affected system.
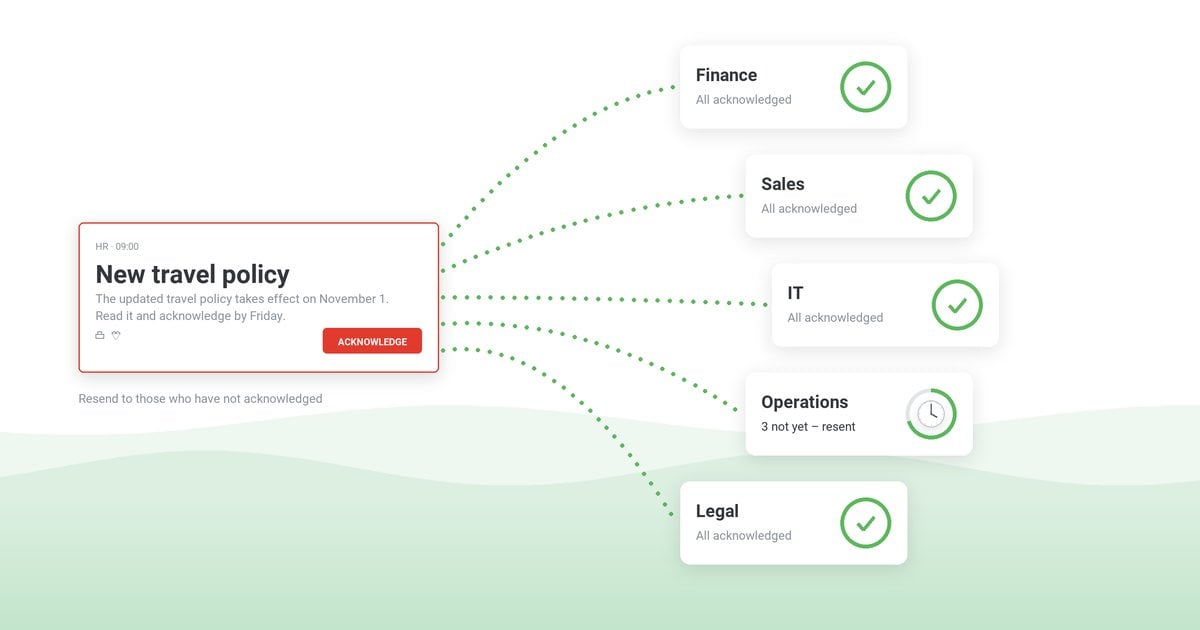
Track and follow up. Whatever sends the notice has to show who has received it and let you resend it to the rest; a distribution list cannot. Our guide to reducing help desk tickets during IT outages covers the help desk side.
Outage notification software turns the plan into saved notices, recipient groups and a resend list
What the nine notices cannot supply on their own has to be in place before the incident is declared, and keeping it ready is what an outage notification system is for – it is what DeskAlerts, our own IT alert software, is built to do.
In the DeskAlerts console, publishers save the nine system outage messages above as drafts, or start from a template, and fill in the placeholders when the incident is declared. If your process requires a second sign-off, switch on the optional approval workflow: each notice then sits in Pending Approval until it is approved by a publisher who holds that role.
Messages go to the whole company or to selected groups, organizational units or IP ranges – for example, only the finance groups when the ERP is down at month-end, or the staff of one site when its file server fails. Where an application’s users do not match a directory group, a group for them can be created in the console beside the synchronized ones. People outside the directory – contractors, agency staff – are not in the synchronized audience. Add them as recipients with a phone number for SMS, or record the gap in the plan rather than discover it during the incident.
What to prepare for each channel:
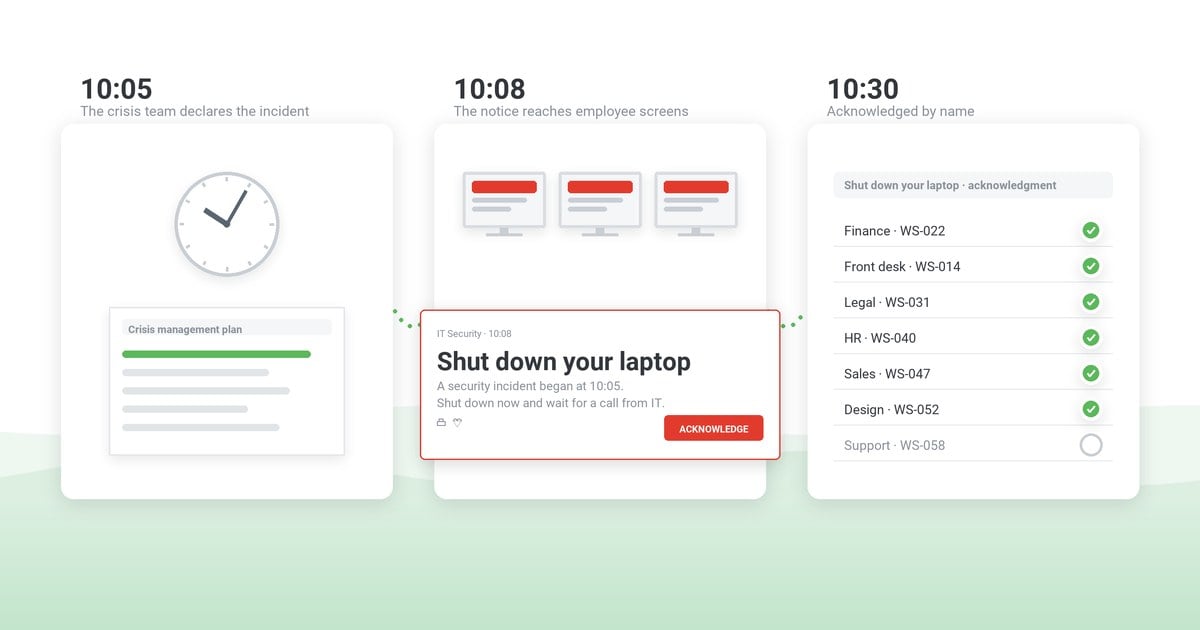
- Pop-up alerts: one saved as a draft with high priority and acknowledgment required – it stays in front of other windows and closes only when the employee clicks Acknowledge.
- Push notifications and SMS text messages: the SMS gateway tested and the mobile app registered on phones in advance.
- Scrolling desktop tickers (Windows 10/11 and macOS only): a status ticker saved as a draft, then duplicated for each update during a long outage.
- Lock screen messages (Windows only): a notice ready to publish, so an outage declared before the workday can already be on locked screens when people arrive.
- Screensavers (Windows only) and digital signage: a status slide ready to publish, and the signage address already open on the screens in shared areas such as the service desk floor or a cafeteria.
Once a notice is out, the reports show who has received it, who has not and who has acknowledged it. A resend can be limited to the people who have not received it, or not acknowledged it. The Users Action Log records the time a publisher pressed Send, which is the evidence behind the time-to-first-notice figure.
Only desktop alerts record an acknowledgment; on the mobile app, receipt counts from the moment the employee opens the alert. Desktop agents and the mobile app must reach the DeskAlerts server, in the cloud or on premises, and SMS and text-to-call leave through your own third-party gateway (Twilio is the documented one). A VPN or sign-in outage that cuts the path to the server takes the desktop and mobile channels with it; a gateway fault takes SMS and text-to-call.
The seven decisions, the approvers and the quiet-week test stay with the plan. The software holds the result; it does not make the decisions.
The channel list and deployment options are on the IT outage notification software page.
After a major incident, review the notices against the timeline: when the first one went out, how many duplicate contacts arrived before and after it, and which groups say they never saw it. Report two numbers to management – time to first notice and duplicate contacts per incident, each against the last similar incident. That is the evidence for changing the plan.
See the nine notices sent as desktop alerts
Watch them go out, then open the report for each one.
Evaluating tools to keep employees informed during outages? See how DeskAlerts compares to other notification tools across features, targeting and reporting.
Frequently asked questions
What is an outage notification?
An outage notification is the notice telling employees that a service is, or will be, unavailable. It is distinct from the customer status page and from the update to the major-incident bridge: the same facts, for a different audience and at a different level of detail. It applies to planned maintenance and unplanned incidents alike; the system outage notification samples above cover both.
What is a significant service outage?
A significant service outage is one your priority matrix rates as high impact and high urgency – typically a critical service down for many users or a whole site – and it usually triggers the major-incident process, with its own communication cadence. In regulated sectors it can also trigger reporting to a regulator: in EU financial services, for example, financial entities such as banks, insurers and investment firms must report major ICT-related incidents to their competent authority under DORA (applies since January 17, 2025). Agree on the criteria and the notices with compliance beforehand.
What is the best communication tool for IT teams to receive alerts about system outages?
Two different kinds of tool answer that question. On-call and monitoring tools page the engineers who will fix the fault; outage notification software tells the employees who are affected, through channels chosen so that they do not rely on the failed system, and reports who has not received the notice. DeskAlerts is the second kind. Many organizations run both, working from the same major-incident record.
What should a reason for outage message include?
A reason for outage (RFO) message should give the date and duration of the outage, the systems and groups affected, the cause in plain language, what IT did to restore service, what will change to prevent a repeat, and any action employees still need to take. The reason for outage template above follows that order.
How often should you send updates during an IT outage?
A workable cadence: a priority 1 incident gets an update every 30 minutes or at each change of status; a priority 2, hourly; a priority 3, or a degradation with a working workaround, at milestones. Each update goes out when the previous one promised; once the service is stable, the plan may lengthen the interval, and the notice says so.

 Steve Wilson: Oct 23, 2026, 9:00:00 AM